Canonical has published a preliminary version of the Myna speech recognition system and voice text input tools built on its basis, integrated into Ubuntu. Ready-made assemblies are generated for Ubuntu 24.04 LTS, Ubuntu 26.04 LTS and Ubuntu 26.10 in packages for amd64 and amd64v3 architectures. Supports work in GNOME environments using the Wayland protocol. For speech recognition, a choice of AI models Whisper, Parakeet or Funasr can be used, running locally and supporting different languages.
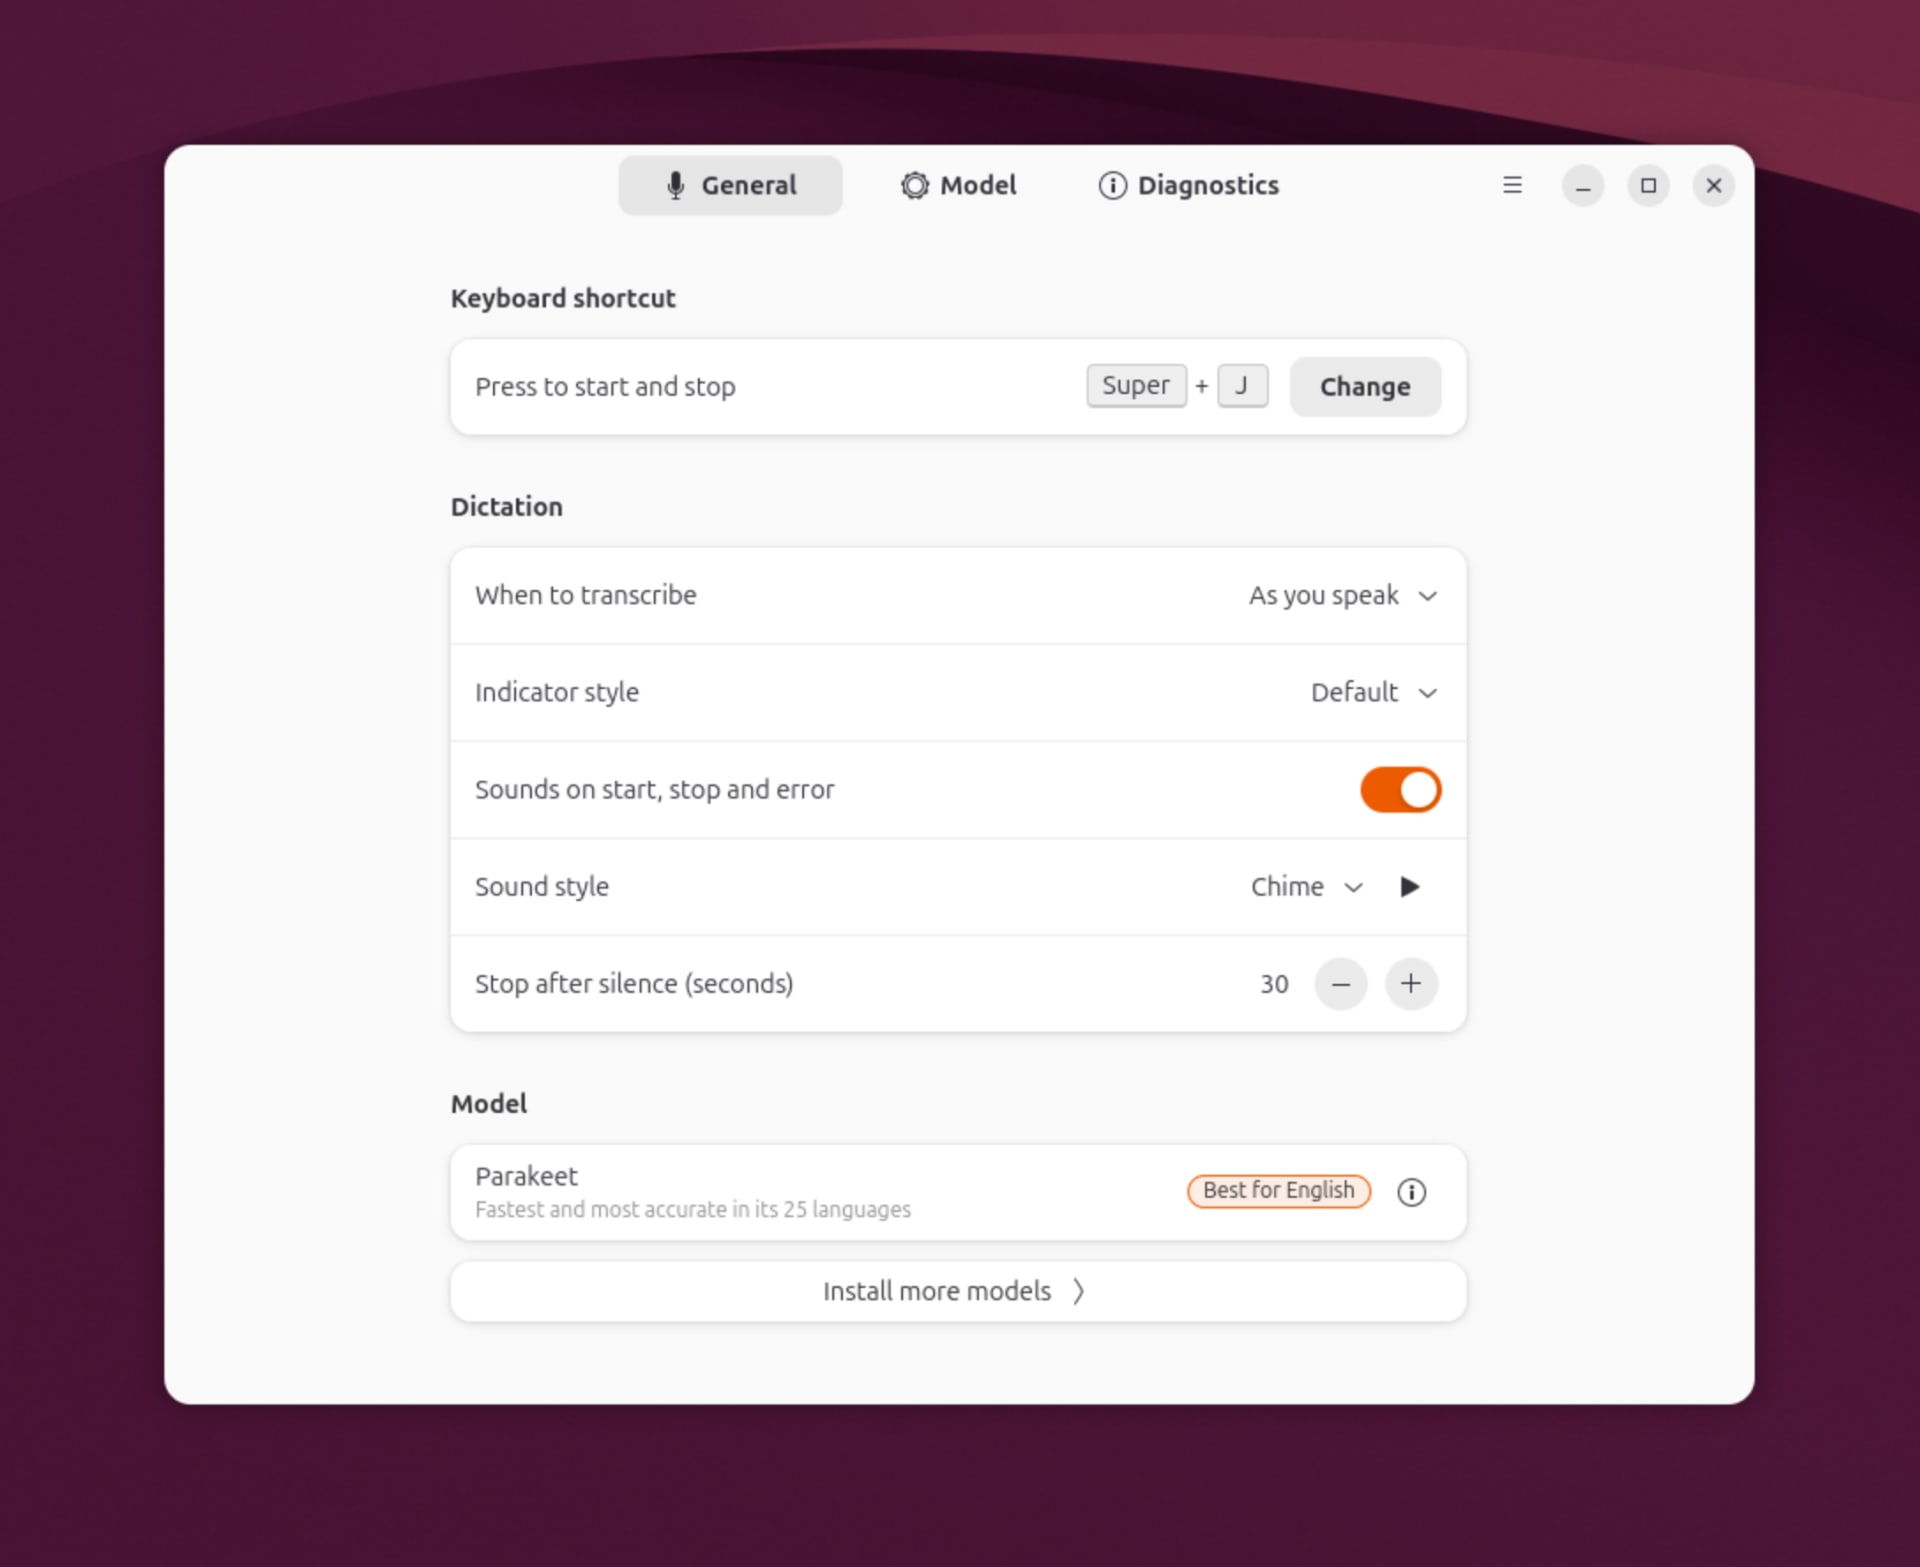
An add-on to GNOME Shell, Myna Shell, has been prepared for integration with the desktop. Voice input is activated by the Super+J key combination, after which you can dictate the text out loud and press Super+J again to end the dictation session. The dictated text is inserted into the current application through the simulation of keyboard input.
A section has been added to the configurator for setting up the activating key combination, indicating the start/stop of recognition, auto-shutdown after a certain time of silence and a text substitution mode (as you speak or immediately after the dictation is completed), as well as selecting an AI model. An engine is provided for hardware acceleration of speech recognition models on systems with NVIDIA GPUs (other acceleration options will appear later).
Installation is done via PPA repository: